Literature review matrix
Find papers with Google Scholar, record each one as a row in a spreadsheet, and know when to stop searching. Includes a blank template and a worked example.
A literature review matrix is a spreadsheet with one row per paper and one column per thing you want to know about each paper: its research question, data, method, results, and limitations. Filling it in forces you to read each paper for the same information. Sorting it later, you’ll spot patterns across papers that are hard to see one PDF at a time. Raul Pacheco-Vega called this the conceptual synthesis Excel dump, and his site has many more literature review resources.
Find papers with Google Scholar
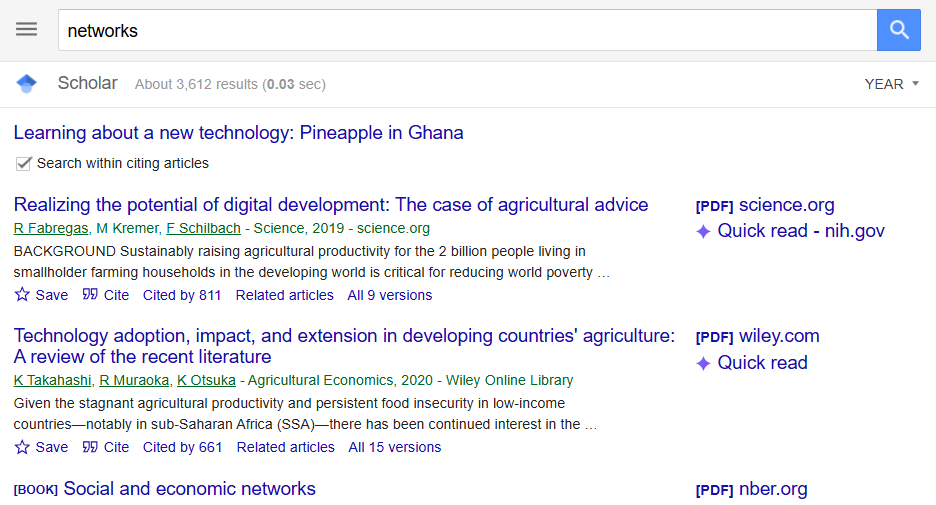
Most students, in my experience, use Google Scholar as a search box and rarely click anything below a result. Scholar ranks each result by its own criteria, and every result also has links and tools below it that most students rarely click.
Know how Scholar orders results
Google says that Scholar “aims to rank documents the way researchers do, weighing the full text of each document, where it was published, who it was written by, as well as how often and how recently it has been cited in other scholarly literature.” By those criteria, Scholar judges the results on page nine less relevant than those on page one. A paper that other scholars rarely cite may still be the right paper for you, so don’t stop looking after the first page or two. A recent paper hasn’t had time to accumulate citations. If other scholars rarely cite an older paper, ask yourself why they pass it over.
Use the links and tools around each result
- Cite: the quotation-mark icon gives you a formatted citation in several styles, plus a BibTeX export for LaTeX users
- Related articles: lists papers that Scholar’s algorithm judges similar to the one you found, and is most helpful at the start of a review
- Cited by: lists the papers Scholar has found that cite this one, so you can move forward in time from an older paper to the newer work that builds on it
- Search within citing articles: on the “Cited by” page, this checkbox restricts your search to the citing papers
That last option is one of the most powerful tools Scholar offers. Suppose you know one or two seminal papers on a topic but not the recent evidence. Open the seminal paper’s “Cited by” list, check the box, and search for your keywords: you’ll see only the citing papers that also match your keywords.
Advanced search and other tools
Scholar’s advanced search is in the side drawer (the menu icon at the top left). It lets you search the author, title, and publication fields separately, and limit results to a range of years. Field searches help when your keywords are also common surnames. If you want papers about wolves and hunting, you probably don’t want everything written by a Dr. Hunt or a Professor Wolf.
A library link to the full text appears next to a result when your university has a subscription and either you’re on campus or you’ve set up library links in Scholar’s settings. The envelope icon on a results page creates an email alert, so Scholar tells you when new papers match your search.
Look for data too
Google’s Dataset Search finds datasets rather than papers. Not everything it lists is freely accessible, but you can use it to check which data sources exist for a topic. For ready-made public statistics, try Data Commons.
Build the matrix
Start from the template below, which has three sheets: a matrix with the columns below, a quotes sheet, and one describing each column.
To use it in Google Sheets, open a new sheet and choose File, then Import, then Upload.
Keep it tidy
Put one paper in each row and one piece of information in each column. Never stack two kinds of information in one cell, such as the data source and the method, because you’d no longer be able to sort or filter on either. If a paper uses two datasets, list both in the data_source cell, separated by semicolons; don’t create a data_source_2 column. Keep column names short, lowercase, and free of spaces, so the sheet also reads cleanly into Stata, R, or Python. Verbatim quotes are rare in economics; when a phrase is especially striking, record it exactly, with its page number. The template’s separate quotes sheet has these columns, one row per quote: citation (matching the matrix sheet’s citation column), page, and quote.
Example: air pollution and health
Ayal Weiner-Kaplow built this matrix of 44 papers on air pollution and health, to inform a study of how fine particulate matter affects cognition in Kenya. I restructured it into tidy form, with one piece of information per column. The original file had merged sample, data source, and method into one column, and pollutant and measurement method into another.
| Paper | location | time_period | explanatory | outcome_measure | identification |
|---|---|---|---|---|---|
| Adhvaryu et al. (2016) | Western Sub-Saharan Africa | Aug. 1985-Dec. 2006 | PM2.5; dust | Child mortality rates | Panel |
| Arceo, Hanna, and Oliva (2016) | Mexico: many municipalities of Mexico City | 1997-2006 | PM10; O3; SO2; CO | Weekly, municipality-level, mortality rates | Instrumental variables |
| Bharadwaj et al. (2017) | Santiago, Chile | births between 1992-2001 and corresponding test scores between 2002-2010 | PM10; O3; CO | National 4th grade test score | Panel |
| Chang et al. (2016) | Northern California | 2001-2003 | PM2.5; PM10; NO2; O3; CO | Worker Productivity | Panel |
| Chay and Greenstone (2005) | United States | 1969-1990 | TSP | Measure of pollution impact: Housing prices | Instrumental variables |
The preview shows five of the 44 rows and six of the 20 columns; the downloads have the rest.
Columns to include
I always include the columns below, whatever your topic; you may want extra ones depending on what you’re studying.
| Column | What goes in it |
|---|---|
citation | Full citation for the paper |
year | Publication year, in its own column so that you can sort by it |
research_question | The main research question, in one sentence. For example: “What is the relationship between dust exposure in utero and child mortality in West Africa?” |
outcome | The main outcome variable, in words (infant mortality, test scores, yields) |
outcome_measure | How the paper measures the outcome: the source, unit, and time frame (deaths before age one, from birth histories) |
explanatory | The main explanatory variable |
explanatory_measure | How the paper measures the explanatory variable |
method | The empirical method, which in applied microeconomics is typically the identification strategy: panel data with fixed effects, instrumental variables, regression discontinuity, a randomized trial, or a natural experiment that provides exogenous variation; for a randomized trial, describe the treatment |
data_source | The datasets: a Demographic and Health Survey, a census, administrative records, or the authors’ own survey |
sample | Who or what the data cover, and the population they come from. Knowing the population and how the sample was drawn helps you judge how far the results generalize |
sampling_method | How units entered the data: a random sample, a census of all units, program participants, or a convenience sample |
key_results | The main estimates, with their size and units |
limitations | The limitations the authors acknowledge, plus any you notice yourself: threats to identification, measurement problems, a sample that may not generalize |
related_articles | Other papers in your matrix that this one builds on, replicates, or contradicts. Linking papers is an art, not a science |
comments | Anything else, including how the paper relates to your own project |
Other potentially useful columns
Add location (countries or regions) when your papers span many settings. Add time_period (the years the data cover) regardless of how many settings your papers span. The outcome_measure and explanatory_measure columns above are where you record how studies measure the outcome or the explanatory variable, whenever they measure it in very different ways. Air pollution measures vary widely across studies, as these examples show:
- Hourly ozone (O₃), carbon monoxide (CO), and nitrogen dioxide (NO₂), and averages of PM2.5 and PM10, from a California Air Resources Board monitor 2.7 miles from a pear-packing factory (Chang et al. 2016)
- Weekly averages of CO, O₃, and PM10, weighted across all monitors within 20 miles of the mother’s residential zip code in a study of birth outcomes (Currie and Neidell 2005)
- Daily aerosol index for subdistricts of Indonesia, from 226 satellite grid points about 175 kilometers apart that cover roughly 3,700 subdistricts (Jayachandran 2009)
Know when to stop searching
I tell students to watch for the same papers turning up again and again, both in the reference lists you’re reading and in your own new searches that lead back to sources already in the matrix. When that happens, you’re starting to be in good shape.
Pacheco-Vega named this concept saturation too, a term he borrowed from qualitative research methods. He put it this way: “I define concept saturation as the point where I am seeing the same citations repeated on a regular basis.”
In a 2017 post on how much reading is enough, he wrote: “I don’t think you gain too much, marginally, from reading yet another paper on the same topic but using a different case study.” He was upfront, too, that the question has no clean answer. In your matrix, that saturation will look like new rows that repeat values you already have in method, data_source, or explanatory.